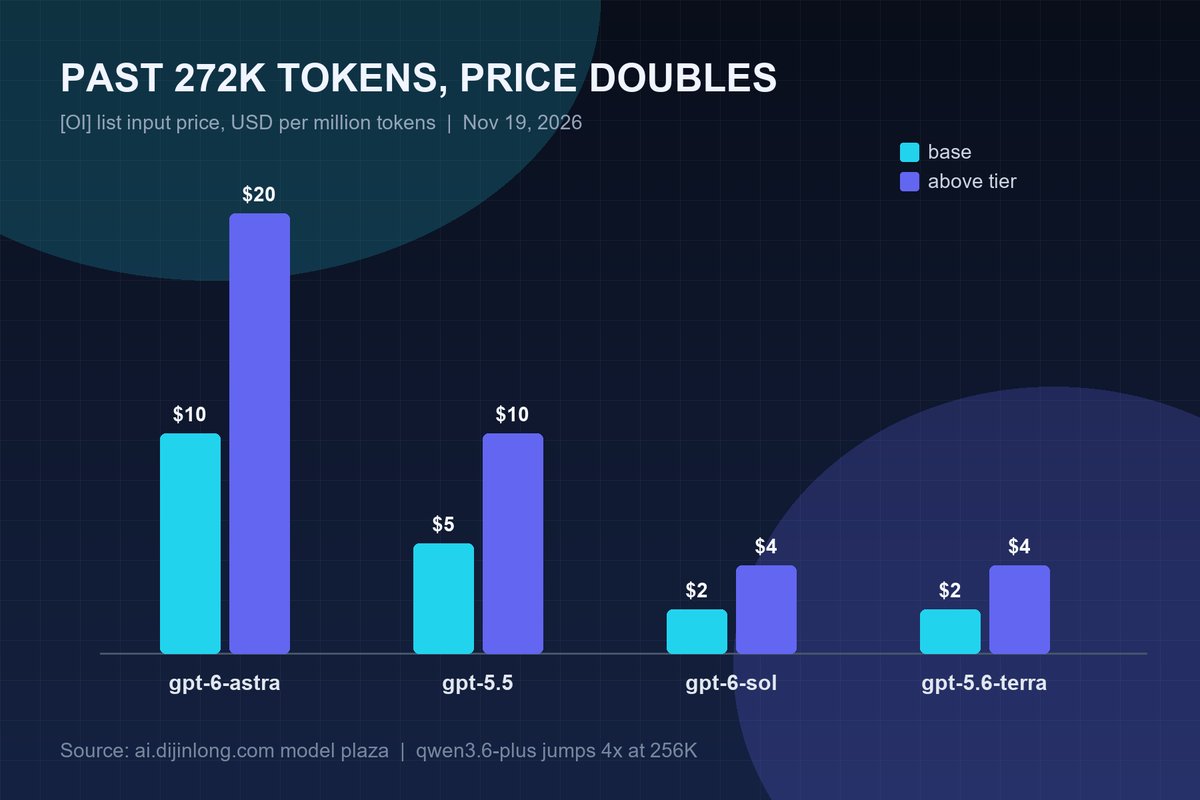
A million-token context window is a capacity claim, not a price. Of the 53 text models on sale here, 37 advertise a window of a million tokens or more, but the ones with length-based tiers raise their input rate the moment you cross a threshold. gpt-6-astra jumps from $10 to $20 past 272,000 tokens. qwen3.6-plus jumps from 2 yuan to 8 yuan past 256,000, a clean 4x. On long documents, picking the wrong model costs more than picking the wrong tier. Figures are current as of November 19.
The table below copies the tier prices straight from the plaza, with no rounding.
| Model | Context | Base (in / out) | Tier starts | Above tier (in / out) | Multiplier |
|---|---|---|---|---|---|
| gpt-6-astra | 1.05M | $10 / $50 | > 272K | $20 / $75 | 2x input, 1.5x output |
| gpt-5.5 | 1.05M | $5 / $30 | > 272K | $10 / $45 | 2x input, 1.5x output |
| qwen3.6-plus | 1M | 2 CNY / 12 CNY | > 256K | 8 CNY / 48 CNY | 4x on both |
| glm-4.7 | 205K | 2 CNY / 8 CNY | 32K to 200K | 4 CNY / 16 CNY | 2x on both |
| glm-5 | 205K | 4 CNY / 18 CNY | >= 32K | 6 CNY / 22 CNY | 1.5x input, 1.22x output |
| glm-5.1 | 205K | 6 CNY / 24 CNY | >= 32K | 8 CNY / 28 CNY | 1.33x input, 1.17x output |
| glm-5-turbo | 203K | 5 CNY / 22 CNY | >= 32K | 7 CNY / 26 CNY | 1.4x input, 1.18x output |
Three patterns. [OI] models all draw the line at 272,000 tokens with identical multipliers, 2x input and 1.5x output. Zhipu's glm line draws it far earlier, at 32,000, with gentler multipliers around 1.5x, which means ordinary long conversations already cross it. qwen3.6-plus is the outlier at 4x, and it doubles both input and output.
Two more models do not itemize tiers on the price sheet, though their official notes are explicit: gpt-6-sol and gpt-5.6-terra both bill 2x input and 1.5x output past 272,000 tokens.
Input doubles while output rises only 50 percent because the added cost sits in prefill, where the whole prompt is encoded into cache. Decoding does not slow proportionally. The practical consequence is that long-input, short-output jobs get punished hardest: feeding 300,000 tokens in to get 500 words of summary is the worst possible trade.
The glm 32K tier looks gentler, but it hits short outputs just as hard. Input rises from 4 to 6 yuan while output climbs from 18 to 22, so both ends move at once.
One detail worth knowing: tiers are judged per request, not on cumulative traffic. Splitting a 300,000-token document into ten 30,000-token calls sidesteps the 272K tier entirely, but the same split trips the 32K line on every glm call, which makes it more expensive, not less.
Take one 300,000-token technical manual, fed whole with a 2,000-token answer, and price it at list rates:
| Model | Formula | Cost per run (list) |
|---|---|---|
| gpt-6-astra | 0.3 x $20 + 0.002 x $75 | $6.15 |
| gpt-5.5 | 0.3 x $10 + 0.002 x $45 | $3.09 |
| gpt-6-sol | 0.3 x $4 + 0.002 x $15 | $1.23 |
| qwen3.6-plus | 0.3 x 8 + 0.002 x 48 CNY | 2.496 CNY |
| glm-4.7 | 0.3 x 4 + 0.002 x 16 CNY | 1.232 CNY |
| glm-5.3-flash | 0.3 x 0.8 + 0.002 x 2.8 CNY | 0.246 CNY |
gpt-6-astra costs $6.15 a run. glm-5.3-flash costs 0.246 yuan, about $0.037, a spread of more than 160x. The middle rows carry the lesson: glm-4.7 is a mid-range 200K model whose tier starts at 32K, so the same manual costs 1.23 yuan, while glm-5.3-flash is a single-tier lightweight model with a 1.04 million window that does it for 0.246 yuan, five times cheaper. On long documents, the cheap mid-range model is often the expensive choice.
Worth restating precisely: the tier looks at the input length of a single request, not the running length of a conversation. A request carrying 5,000 tokens never trips the 272K line, even if the thread behind it has accumulated 400,000. What counts is how much context each call actually ships.
Measure tokens before choosing. Run one real document through the API and read input_tokens from the usage block. Estimates run low; 300,000 tokens is already a several-hundred-page manual.
Trim just under the line. Keep input below 260,000 for the 272K threshold and below 30,000 for the 32K threshold. A few thousand tokens of headroom is not worth doubling your rate.
Retrieve and summarize instead of stuffing. Chunk the document and send only the relevant passages. When you need a global view, summarize in passes and combine, which usually costs less than one full-length call.
Cache the stable prefix. gpt-6-astra charges $1 per million tokens for cache reads, a tenth of its $10 input rate. kimi-k3 charges $0.3 to read cache, with cache writes priced at the input rate of $2.9873. System prompts and a fixed manual should be cached, not resent.
One clarification: the marketplace publishes list prices and seller discounts, and buyers pay list times one minus the discount. How tiers fold into that calculation is settled by the charge on your invoice, so verify before scaling a workload.
Two places to look. Model cards on the model plaza show the official price table, with tags like "32K and up" or "over 272K" on tiered models. The model docs carry the vendor's own wording, including multipliers and cache rules.
Check in this order: is the context window big enough, does the model have tiers and where do they start, and is the discount durable. A listing with one seller and no certification can reprice or vanish without notice.
$10 buys 4.55M to 667M input tokens here, a 147x spread. Real discount math, per-request costs, three budget builds, and the traps behind cheap models
GPT-6.2 cuts list prices 20%, yet platform discounts run deeper: gpt-6-astra trades at under 1% of list. What this week's AI price war means for buyer
Prompt caching stores a repeated prompt prefix and bills cache reads at 5-12% of normal input. Real prices, hit conditions, and how to cut your API bi
Twelve Claude versions are on sale. The newest opus-5-5 costs $8.91 a month; the oldest opus-4-6 costs $49.50. Full table and a pick for each workload
gpt-5.6-terra and deepseek-v4.1-flash win on price and reliability; gemini-3.8-flash is fastest. Effective prices, measured speed, and a three-tier pi
 LONG AI