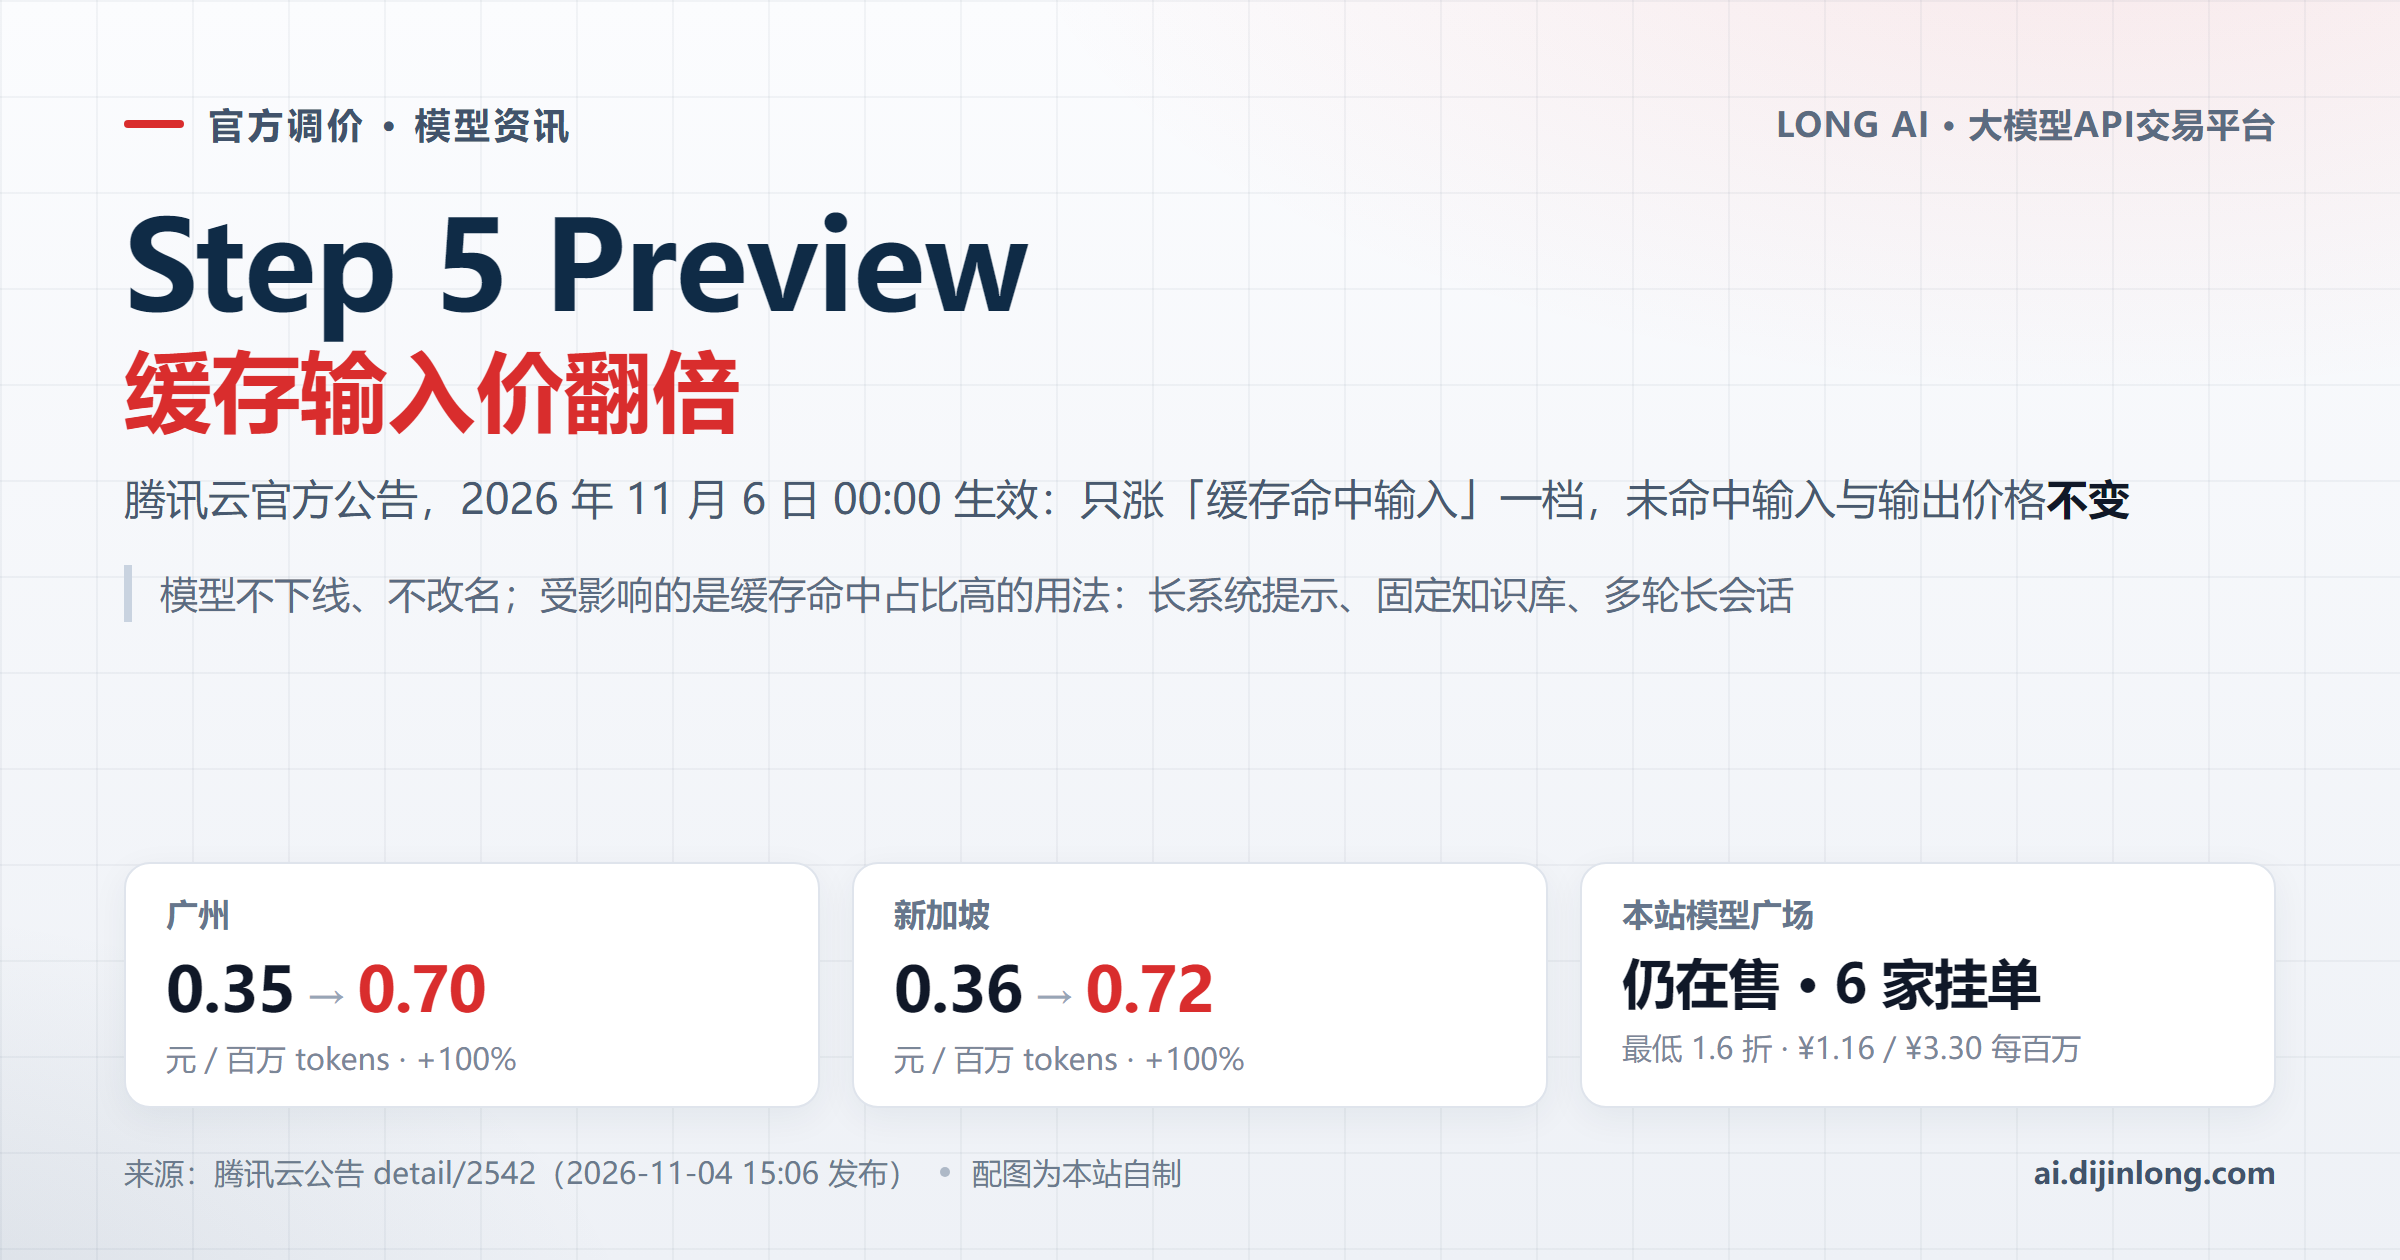
On Nov 4, Tencent Cloud posted a repricing notice: Step 5 Preview (model ID step-5-preview) doubles its "cache-hit input" price, effective Beijing time 2026-11-06 00:00:00. See Tencent Cloud announcement detail/2542, published 2026-11-04 15:06:58. Only this one billing item rises; uncached input and output prices are explicitly "unchanged." No retirement, no rename - the call method stays the same.
| Region | Billing item | Before | After | Change |
|---|---|---|---|---|
| Guangzhou | Cache-hit input | 0.35 yuan / M tokens | 0.70 yuan / M tokens | +100% |
| Singapore | Cache-hit input | 0.36 yuan / M tokens | 0.72 yuan / M tokens | +100% |
| All regions | Uncached input | unchanged (no figure listed) | same | |
| All regions | Output | unchanged (no figure listed) | same | |
The announcement only gives two operational tips: review call volume and cost expectations ahead of time, and set up usage monitoring; discontinue use if you disagree. No transition period, no named replacement - a pure repricing, not a retirement.
A cache hit means multiple requests reuse the same prefix (long system prompts, fixed knowledge snippets, multi-turn history) - that segment skips recomputation and bills at a lower rate. It's exactly this tier going up. High-hit-ratio scenarios are the most sensitive: long system prompts with batch repetitive tasks, RAG fixed documents, long multi-turn sessions. One-off short requests see near-zero change; output-heavy workloads are unaffected too.
A ruler you can compute yourself: new cost = cache-hit volume (M tokens) × 0.35 yuan (Guangzhou) or 0.36 (Singapore). Example: 1,000 M tokens of hits a month, Guangzhou, roughly ¥350 more - reconcilable against the console's usage detail.
At 15:55 on 2026-11-05 we pulled our /api/v1/model-plaza API and cross-checked the page:
step-5-preview returns a card, 6 sellers and 6 quote tiers, page shows lowest 1.6-2.8 off; top-of-page 185 models, 923 listings, average 1.8 off, first listed 2026-10-21.cache_read_price is empty, no separate cache-hit input price - the tier Tencent Cloud just raised isn't an independently visible field on our page.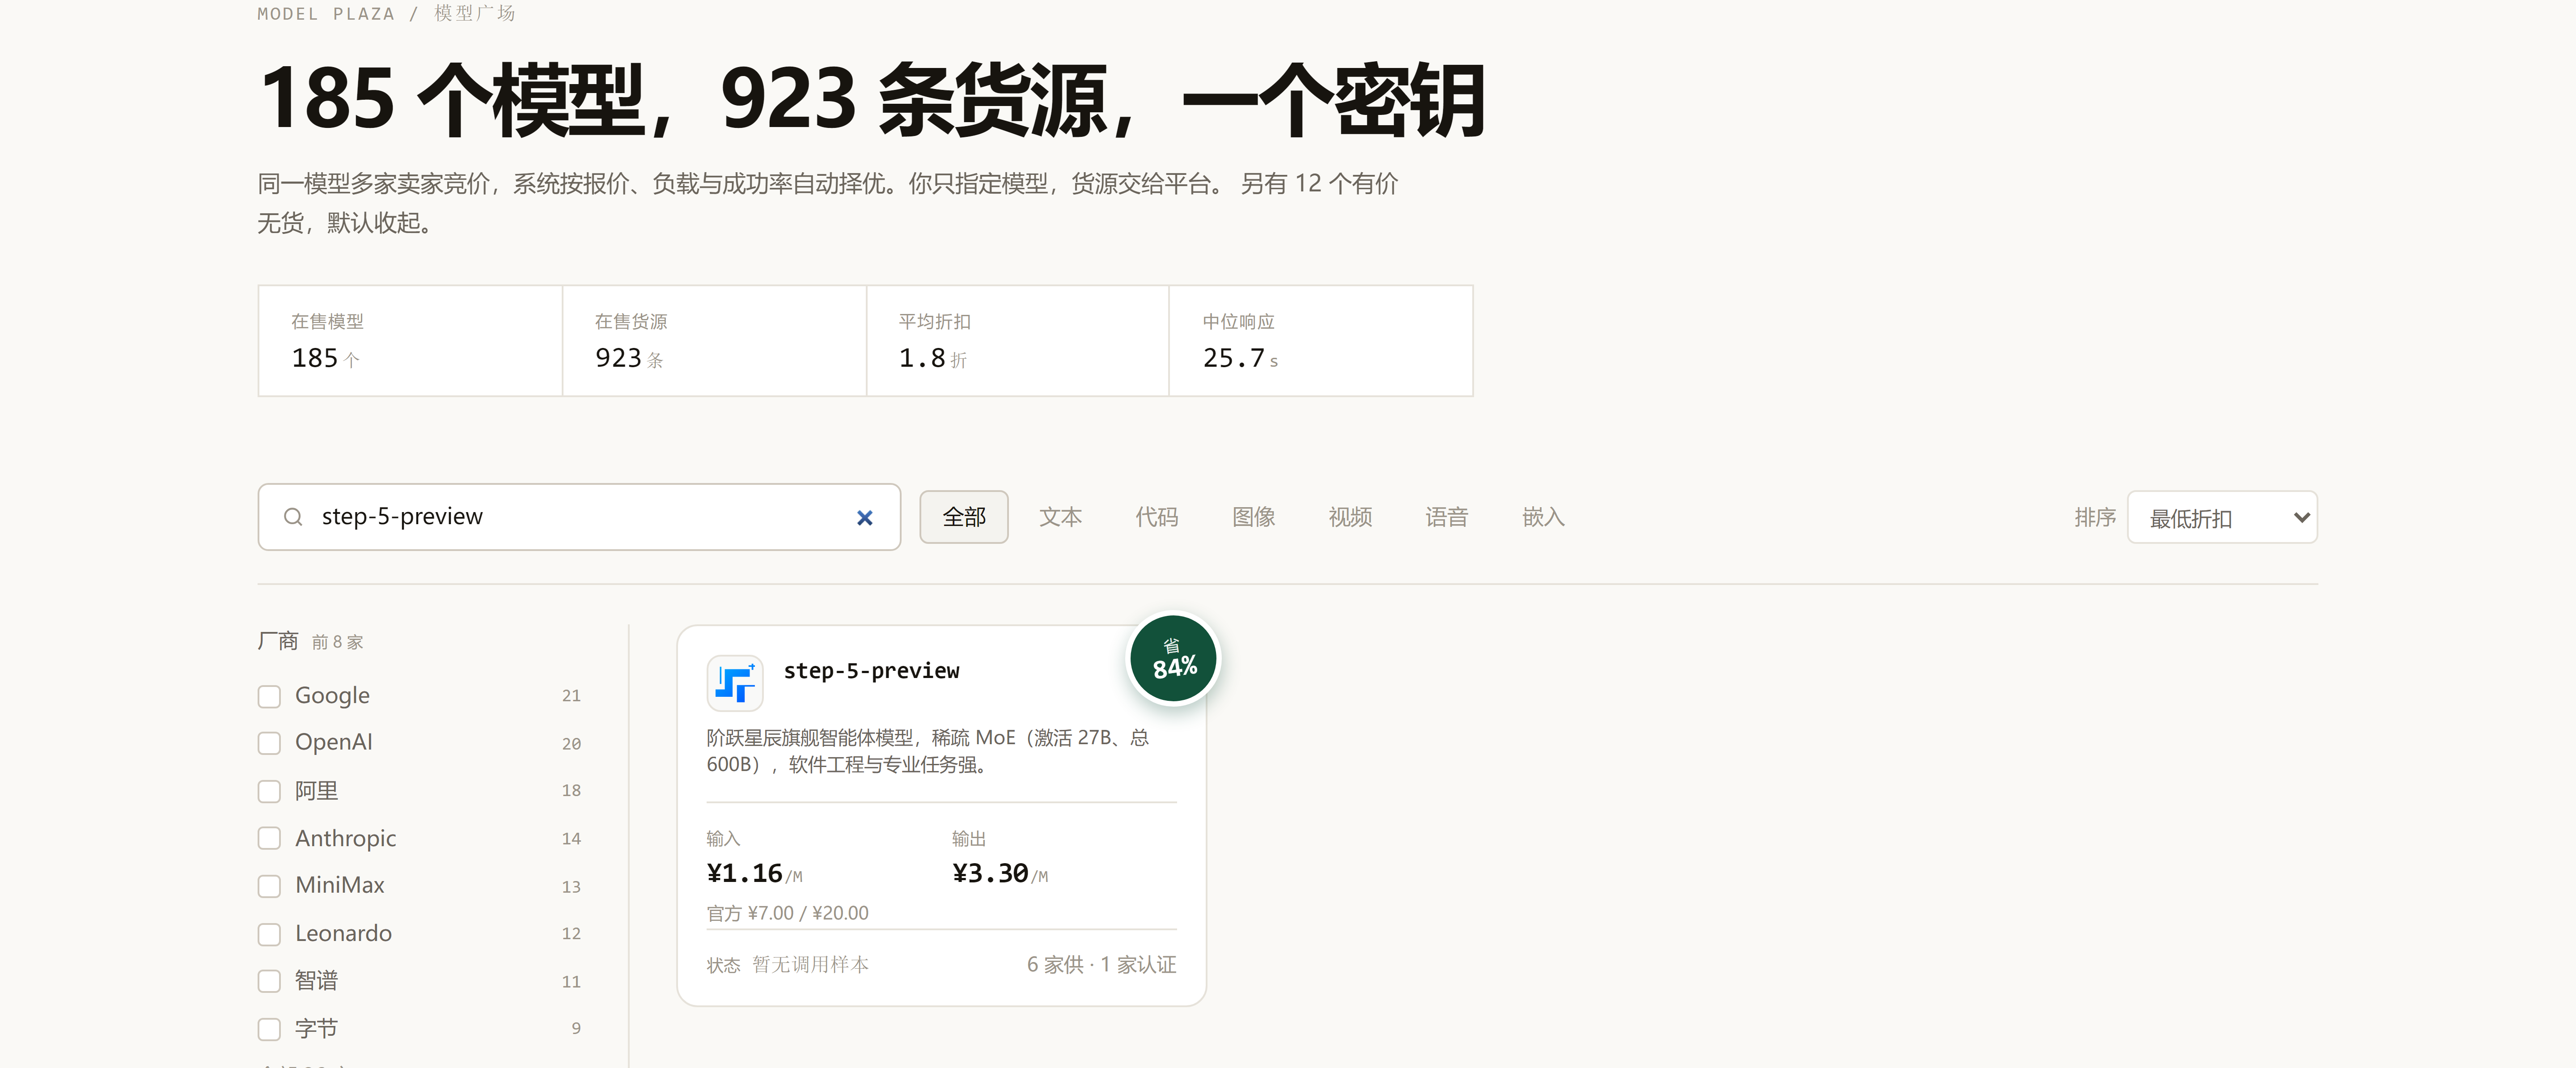
Math you can re-verify (same method as our token billing article): official base is USD $1.04556 / $2.9873 per M tokens, converted at our uniform rate 6.695 to ¥7.00 / ¥20.00; lowest tier buyer_percent_off = 83.5 (page shows 1.6 off). ¥7.00 × 16.5% ≈ ¥1.16, ¥20.00 × 16.5% = ¥3.30, matching the page.
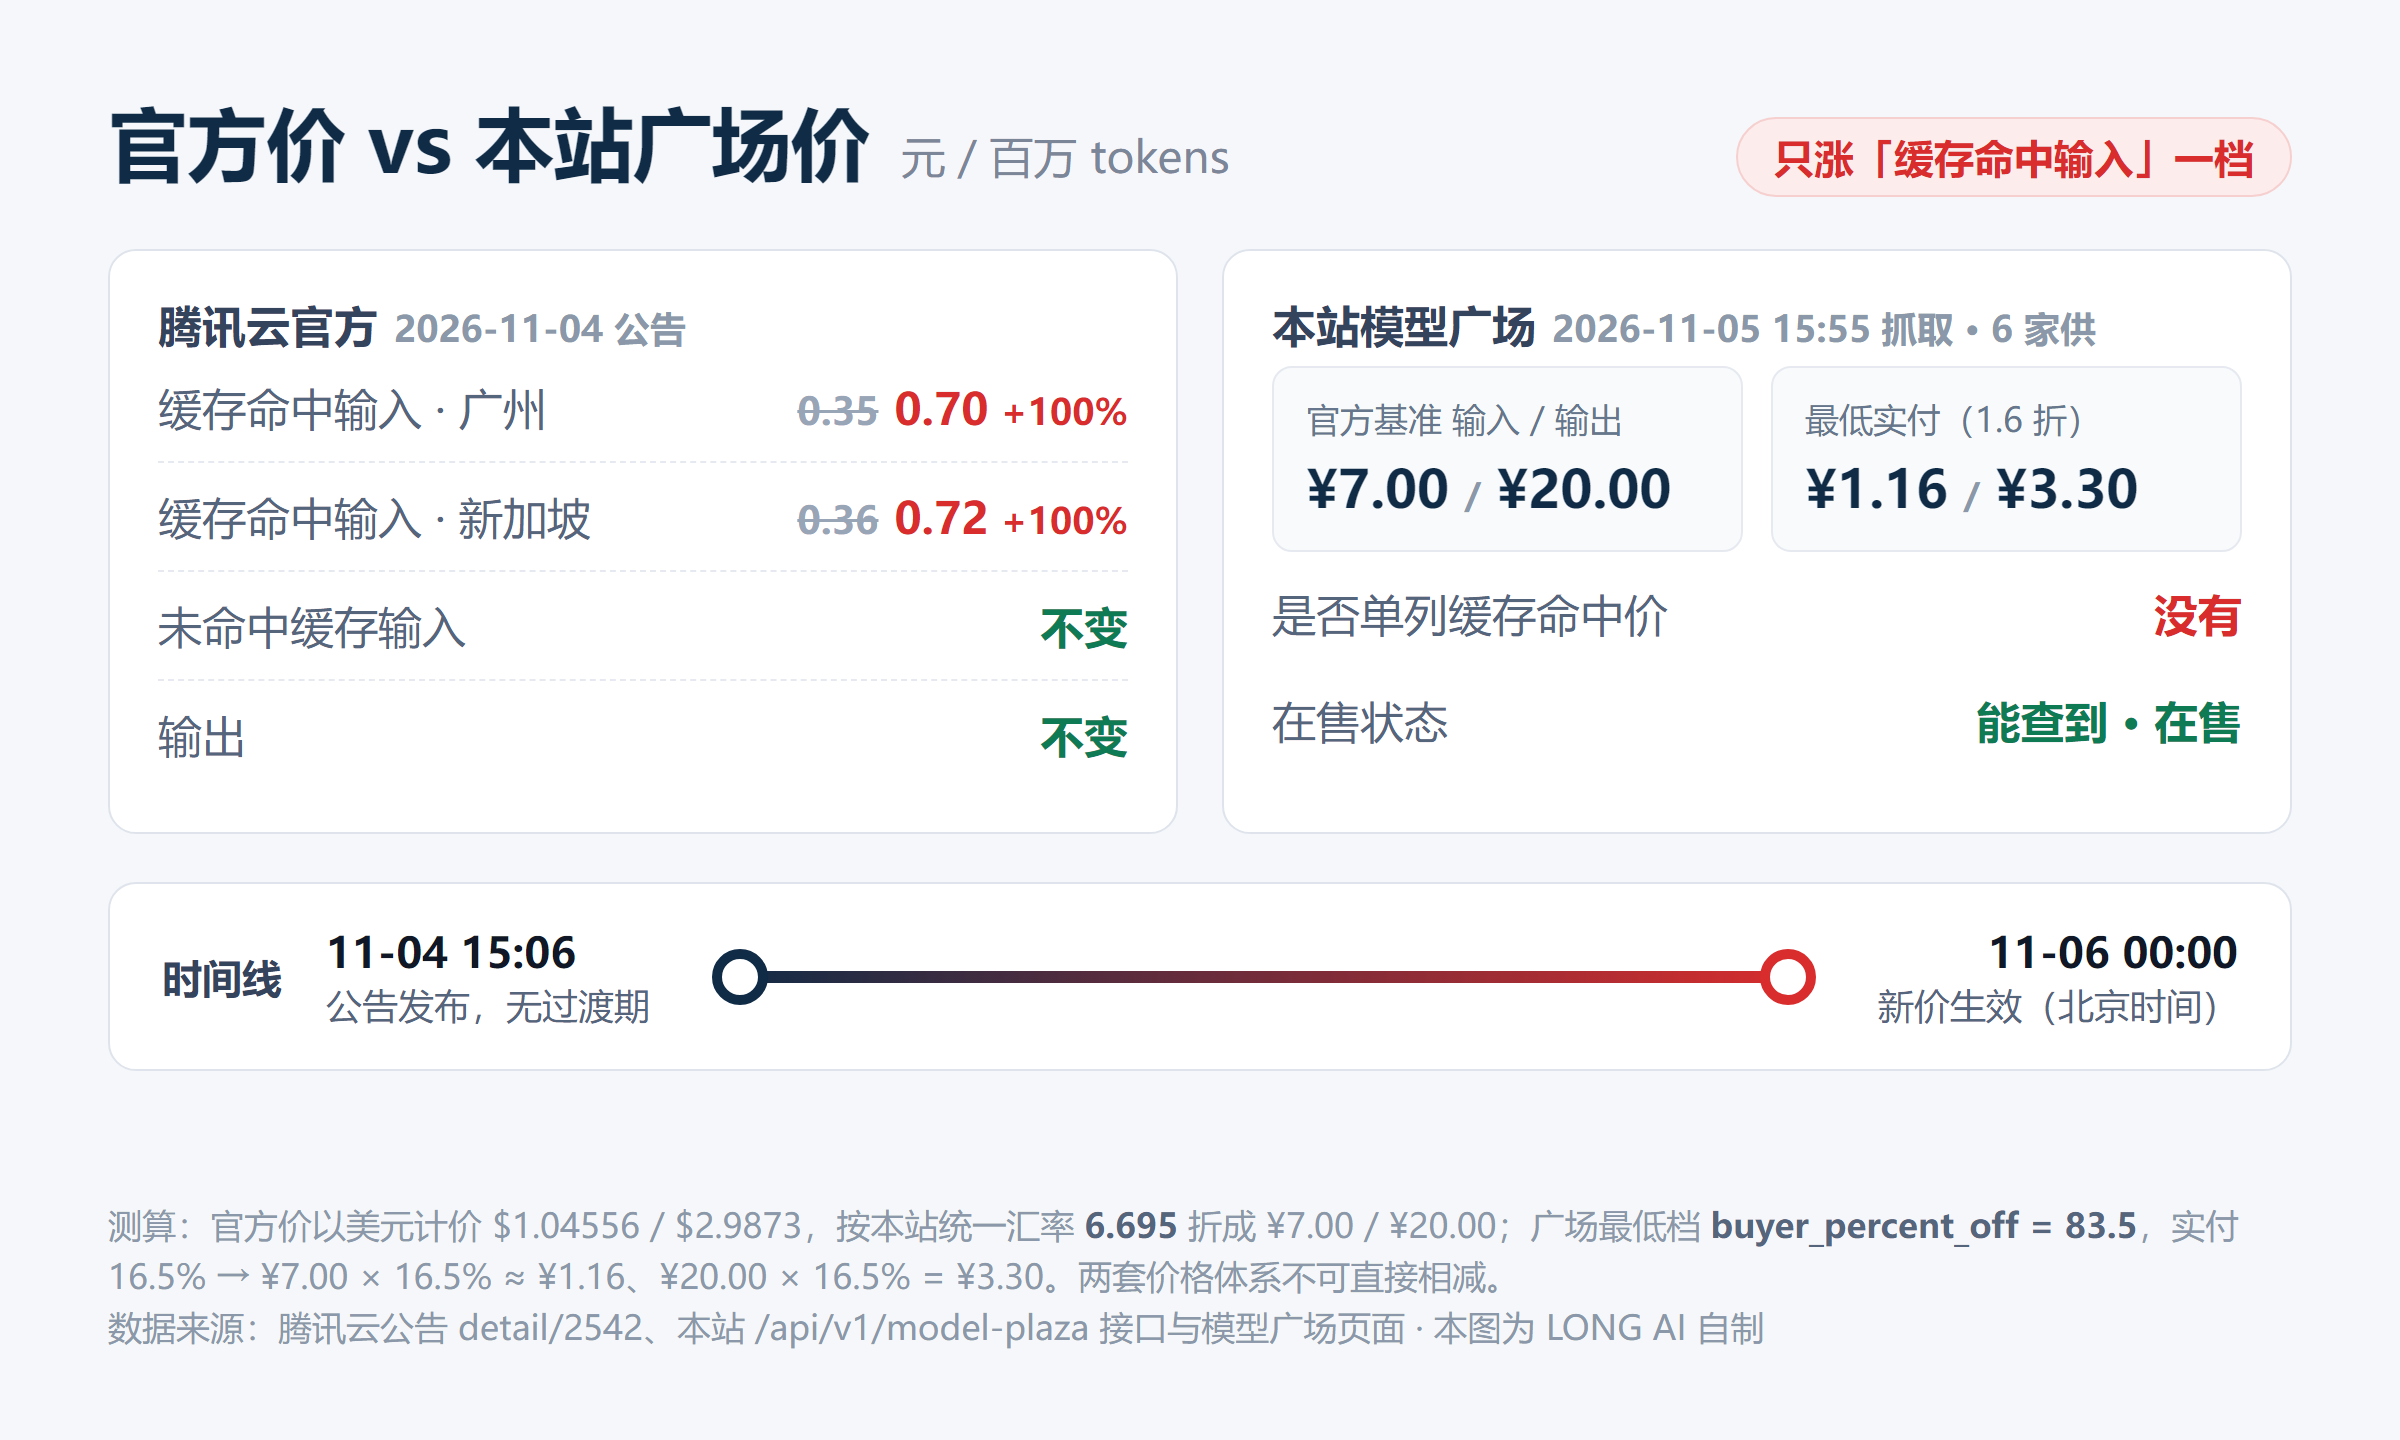
step-5-preview.Official info from Tencent Cloud announcement cloud.tencent.com/announce/detail/2542 (published 2026-11-04, effective 2026-11-06 00:00:00), figures copied verbatim; plaza price and in-stock status from our /api/v1/model-plaza API and page, fetched 2026-11-05 15:55. Tencent's list price and the seller-bid plaza price are two separate systems - you can't subtract them to say "how much cheaper"; this article reports only price and verifiable availability, not quality or speed. Plaza price moves with supply in real time; the final price follows the model plaza page. Images are our screenshots or self-made.
GPT-6.2 cuts list prices 20%, yet platform discounts run deeper: gpt-6-astra trades at under 1% of list. What this week's AI price war means for buyer
Prompt caching stores a repeated prompt prefix and bills cache reads at 5-12% of normal input. Real prices, hit conditions, and how to cut your API bi
Twelve Claude versions are on sale. The newest opus-5-5 costs $8.91 a month; the oldest opus-4-6 costs $49.50. Full table and a pick for each workload
gpt-5.6-terra and deepseek-v4.1-flash win on price and reliability; gemini-3.8-flash is fastest. Effective prices, measured speed, and a three-tier pi
Point your base URL at the platform and one key covers all 138 on-sale models across 51 vendors, in both OpenAI and Anthropic request formats. Copy-pa
 LONG AI