At 10:00 on the morning of Nov 11, Alibaba Cloud Bailian's "model listing and updates" page gained a row: qwen4-max-preview. This is the first time the Qwen4 generation has an official docs page - the Oct 31 practitioner warm-up and the Nov 4 repo/model leak were only rumors before this.
But the same announcement carries two easily-skipped restrictions: Token Plan only, no pay-as-you-go; the preview runs 11-11 10:00 to 11-25 24:00, retiring after. In other words, it's a trial window that closes in fourteen days, not a new model to wire into production.
reasoning_effort across low / medium / xhigh, default xhigh; can't set together with thinking_budget.token-plan.cn-beijing.maas.aliyuncs.com. A normal pay-as-you-go Bailian key can't call it.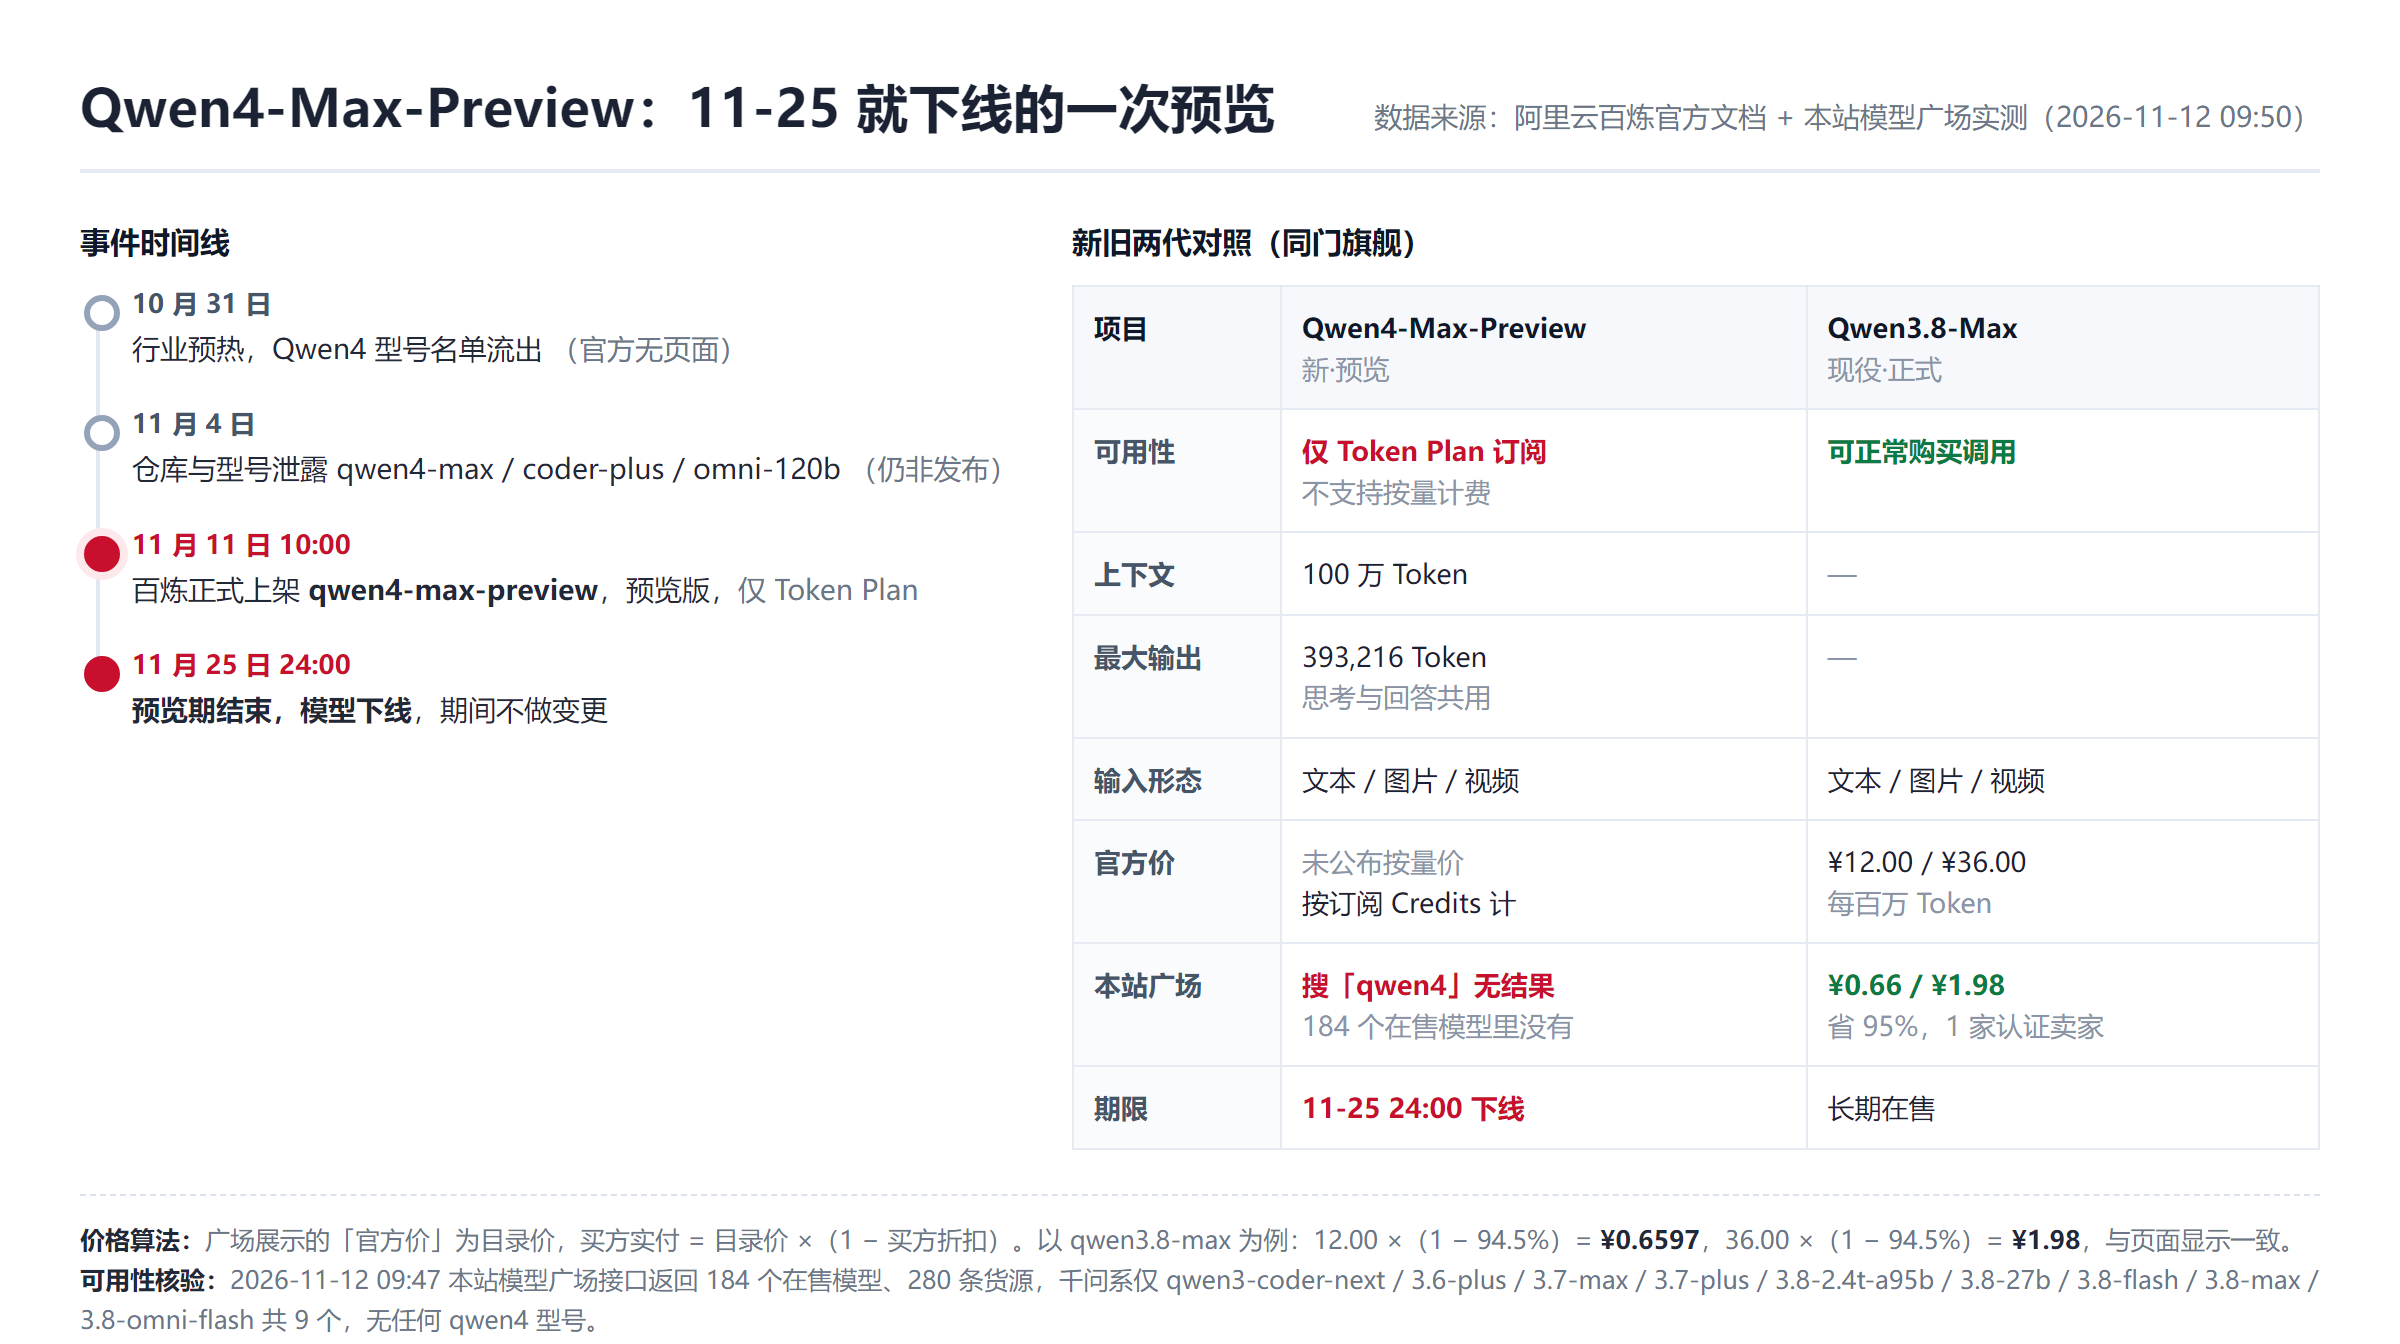
First, can you use it. Yes, but the gate moved. Your pay-as-you-go Bailian key won't work; you must subscribe to Token Plan (personal or team; monthly, quarterly, or annual), then generate a plan-specific key in the console. (Subscription contracts differ from pay-as-you-go; read the cancellation terms first.)
Second, you can't price it per token. The official side gives no per-unit price for this model; Token Plan meters everything in Credits. So you can't compute "how much per million tokens" - only "how many jobs per package." That's completely different from qwen-max's "input cost X, output cost Y" intuition - if you want to compare prices, there's nothing to compare against here.
Third, should you switch. Don't switch it into production. It retires at 24:00 on Nov 25; write the model name into code and it's guaranteed to error two weeks later, and the official side says "no changes during the window" - not even a patch window.
One more biting detail: from qwen4-max-preview on, max_tokens and max_completion_tokens become equivalent, both capping the "thinking + answer" total. If old code only reserves budget by answer length, enabling thinking will truncate early. The official docs call this out separately, meaning users have already tripped on it.
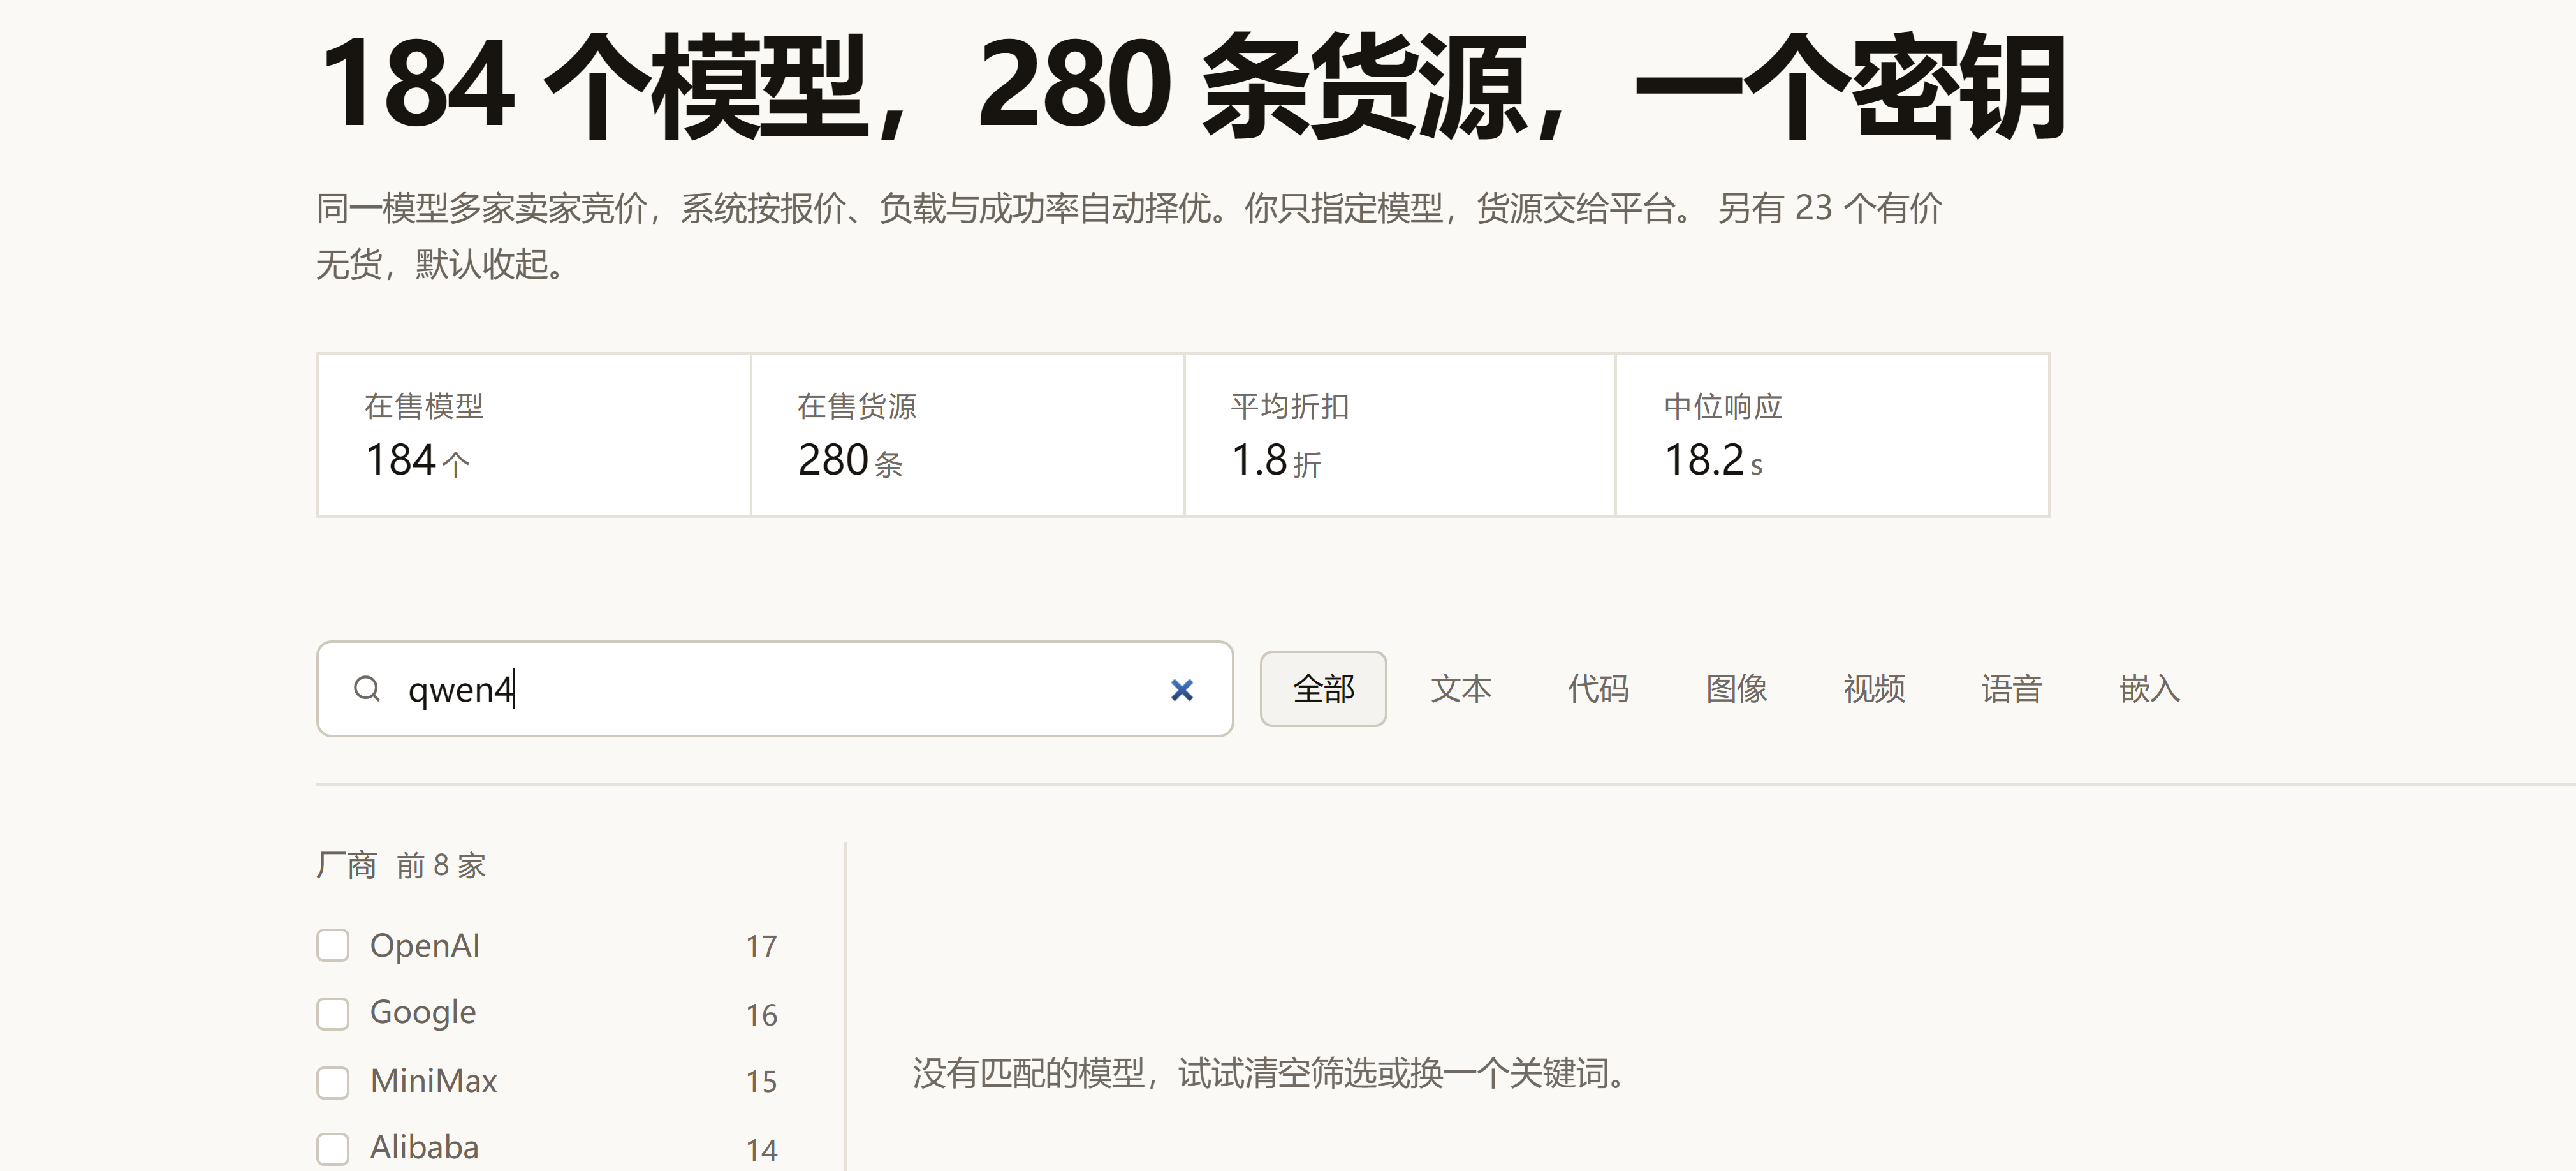
At 09:47 on 2026-11-12, we pulled our plaza API: 184 in-stock models, 280 listings. The Qwen family has 9 on sale - qwen3-coder-next, qwen3.6-plus, qwen3.7-max, qwen3.7-plus, qwen3.8-2.4t-a95b, qwen3.8-27b, qwen3.8-flash, qwen3.8-max, qwen3.8-omni-flash - no qwen4 model at all. Typing "qwen4" into the plaza search returns "no matching models."
For price comparison, the same-family current flagship qwen3.8-max is more relevant. It has 1 verified seller today, labeled 95% off, page shows ¥0.6597/M in and ¥1.98/M out, official list ¥12.00 / ¥36.00. The math: 12.00 × (1 − 94.5%) = 0.6597, 36.00 × (1 − 94.5%) = 1.98. That's the buyer's actual price, matching the page.
preserve_thinking is on by default, so multi-turn must pass the full reasoning_content from history assistant messages back, not merge it into content; plus the max_tokens budget merge above.Official info from the three Alibaba Cloud help pages (model page updated 2026-11-11 20:44), spec, dates, and restrictions verbatim. Our availability from the /api/v1/model-plaza API and plaza page test (2026-11-12 09:47), page scope. CNY prices are plaza actual prices, math shown in the body. This article did not test Qwen4-Max-Preview's speed or quality - no pay-as-you-go access and not our in-stock supply, so no "who's stronger" judgment and no vendor self-reported scores relayed. Images are our screenshots and self-made. For billing questions, see how tokens add up.
GPT-6.2 cuts list prices 20%, yet platform discounts run deeper: gpt-6-astra trades at under 1% of list. What this week's AI price war means for buyer
Prompt caching stores a repeated prompt prefix and bills cache reads at 5-12% of normal input. Real prices, hit conditions, and how to cut your API bi
Twelve Claude versions are on sale. The newest opus-5-5 costs $8.91 a month; the oldest opus-4-6 costs $49.50. Full table and a pick for each workload
gpt-5.6-terra and deepseek-v4.1-flash win on price and reliability; gemini-3.8-flash is fastest. Effective prices, measured speed, and a three-tier pi
Point your base URL at the platform and one key covers all 138 on-sale models across 51 vendors, in both OpenAI and Anthropic request formats. Copy-pa
 LONG AI